TL;DR. FLUX 3 Image Klein ships the FLUX.2 autoencoder unchanged, so a tiny decoder trained for that latent space works for FLUX 3. I fine-tuned TAEF2 on 25.8k real photos with L1 + LPIPS + a light PatchGAN loss and weight averaging. The result, Tiny Klein 3 VAE, has 2.7M parameters instead of 84M, decodes 11× faster at 1024² with about 4× less memory, and its perceptual gap to the full VAE (LPIPS) is 26–32% smaller than TAEF2’s on FLUX 3 generations. It is still visibly softer than the full VAE in the finest textures. It also works for image editing, including bounding-box edits, as long as the full VAE encodes the reference images. Drag the sliders below and judge for yourself.
- Parameters (vs 84M)
- 2.7M
- Faster decode, 1024²
- 11.2×
- Less memory, 2048²
- 3.8×
- LPIPS gap vs TAEF2
- −26–32%
Table of contents
Open Table of contents
1. Why a tiny VAE?
FLUX 3 Image Klein is a 5.6B-parameter text-to-image and editing model. Like every latent diffusion model it never touches pixels while it denoises: the transformer works on a compressed latent grid, and a separate autoencoder (the VAE) turns that grid into an image at the end. FLUX 3 Klein’s VAE has 84M parameters (34M encoder, 50M decoder) and a self-attention block in the middle of the decoder.
For a single 1024² image from the 50-step base model the decode is cheap: about 0.16 s out of roughly 40 s of generation on an L40S. A tiny decoder is not about that case. It matters when:
- You preview every step. Decoding all 50 intermediate latents with the full VAE adds about 8 s per image; with the tiny decoder it is about 0.7 s.
- You generate large images. FLUX 3 Klein generates natively up to 4K. The full decoder’s attention grows quadratically with resolution: decoding 4096² without tiling took 78 s and 24 GB of extra memory in my test, versus 0.31 s for the tiny decoder.
- You are short on GPU memory or run the distilled 16-step Klein, where decode becomes a bigger share of the total time.
The goal: a decoder small enough to run everywhere, reading exactly the same latents, losing as little quality as possible.
2. FLUX 3 Klein reuses the FLUX.2 VAE
A tiny decoder only works if it reads the same latent space the transformer writes. So the first question was whether FLUX 3 changed the autoencoder.
It did not. The Hugging Face LFS metadata gives the SHA-256 of each weight file without downloading it:
| File | SHA-256 |
|---|---|
flux-3-image-klein-base/ae.safetensors | 868fe7b3…ce8f3 |
FLUX.2-dev/ae.safetensors | 868fe7b3…ce8f3 |
The diffusers copies (vae/diffusion_pytorch_model.safetensors) also match each other, and the two vae/config.json files differ only in the diffusers version stamp. Both describe a 32-channel latent at 1/8 resolution, patchified 2×2 into 128 channels for the transformer.
So anything trained against the FLUX.2 VAE (including TAEF2) already speaks FLUX 3 Klein’s latent format.
3. The latent-space trap
My first test fed the full VAE’s encoder output straight into TAEF2’s decoder. It scored 17.9 dB PSNR, which is badly broken. The latent spread gave it away: the encoder’s latents had a standard deviation of about 1.7, TAEF2’s own about 0.85.
The FLUX pipeline does not hand the raw VAE latent to the transformer. It patchifies it and normalizes each of the 128 channels with the VAE’s stored batch-norm statistics, and it undoes that just before decoding:
TAEF2 was trained on , the transformer’s space, not on the raw . Its diffusers wrapper swaps in an identity batch-norm, so the pipeline’s de-normalization becomes a no-op. Applying the normalization fixed it at once:
| Input to TAEF2’s decoder | PSNR (Kodak) | LPIPS |
|---|---|---|
| raw VAE latent | 17.89 dB | 0.224 |
| normalized latent | 30.69 dB | 0.038 |
Everything below uses .
4. Method
Architecture
I kept TAEF2’s architecture (the flux_2 variant of TAESD) and changed only its weights. The decoder is a plain convolutional network:
- A
tanhsoft-clamp on the latent, then a 3×3 conv to 64 channels. - Four stages of three residual blocks (3×3 conv → ReLU → 3×3 conv → ReLU → 3×3 conv), with nearest-neighbour 2× upsampling + conv between stages. That gives 8× upsampling.
- In the three blocks at latent resolution, a small 1×1-conv GroupNorm branch that injects image-wide statistics. TAEF2 added this to match the FLUX.2 latent accurately.
- No attention and no normalization at pixel resolution. Every layer is 64 channels wide.
That is 1.34M parameters in the decoder, the same again in the encoder, against 49.6M in the full decoder.
Distillation setup
The full VAE encoder is the teacher: it turns each training photo into . The tiny decoder is the student and learns to rebuild the original photo from those latents. Only the decoder is trained. The encoder stays as TAEF2 shipped it; it is only needed for image-to-image and editing.
- L1 keeps colours and structure right. LPIPS (perceptual distance in VGG feature space) punishes the blur that L1 alone produces.
- comes from a small spectral-norm PatchGAN discriminator trained with the hinge loss. It pushes towards real texture rather than an average.
- Latent jitter: in 30% of samples, with , . Real FLUX outputs are never perfectly clean encodings.
- EMA weights: I keep with , and evaluate and save .
Data. 800 DIV2K photos plus 24,997 Unsplash Lite photos at 2048 px. Real photos only, no FLUX outputs. Each sample is resized so its short side is random between the crop size and 3× the crop size, then randomly cropped and flipped. The model sees both fine native-resolution detail and whole-object structure.
Schedule (one NVIDIA L40S, bf16 autocast, AdamW, cosine decay):
| Stage | Steps | Crop | Batch | Peak LR |
|---|---|---|---|---|
| 1. warm-up fine-tune (L1 + LPIPS, DIV2K only) | 3,000 | 512 | 16 | 1e-4 |
| 2a. full data, GAN weight 0.05 | 2,000* | 512 | 16 | 1e-4 |
| 2b. full data, GAN weight 0.01 | 1,000* | 512 | 16 | 8e-5 |
| 3. + EMA, main run | 16,000 | 512 | 16 | 6e-5 |
| 4. high-resolution finish | 3,000 | 1024 | 4 | 2e-5 |
*Stages 2a and 2b are the kept parts of two runs I stopped early; each later stage starts from the best checkpoint of the one before. Section 7 has the details. All in, about 6.5 GPU-hours including the abandoned steps, or roughly $6 of rented compute.
The checkpoint kept at each stage is the one with the lowest LPIPS on the 24 Kodak photos.
5. Results
Quality on real FLUX 3 generations
These are the numbers that matter. I generated images with FLUX 3 Klein base (50 steps), captured the exact latent the pipeline hands to its VAE, and decoded it three ways. The full-VAE decode is the reference. None of these images was used for training or for picking checkpoints.
| Decoder | Set A: 6 images | Set B: 8 images (gallery) | ||
|---|---|---|---|---|
| PSNR ↑ | LPIPS ↓ | PSNR ↑ | LPIPS ↓ | |
| TAEF2 | 30.00 | 0.0342 | 28.87 | 0.0363 |
| Tiny Klein 3 VAE (ours) | 31.45 | 0.0234 | 30.33 | 0.0267 |
| gap closed vs TAEF2 (LPIPS) | −32% | −26% |
Set A is mixed sizes from 1024² to 1088×1920; set B is the 8 gallery images below. Ours beats TAEF2 on all 14 images, by both metrics.
Quality on photographs (Kodak)
Here the reference is the original photo, so the full VAE’s own error is visible too. These numbers are a little optimistic for the tiny models, because Kodak was also used to pick checkpoints.
| Decoder | Params | PSNR ↑ | LPIPS ↓ |
|---|---|---|---|
| Full FLUX 3 VAE | 49.6M (dec) | 34.38 | 0.0137 |
| TAEF2 | 1.34M (dec) | 30.69 | 0.0380 |
| Tiny Klein 3 VAE (ours) | 1.34M (dec) | 31.98 | 0.0306 |
Speed and memory
Decoder only, batch 1, bf16, NVIDIA L40S, no tiling. “Extra memory” is the peak above the model weights.
| Resolution | Full VAE | Tiny Klein 3 VAE | Speed-up |
|---|---|---|---|
| 1024² | 161 ms · 2.4 GB | 14.4 ms · 0.6 GB | 11.2× |
| 2048² | 760 ms · 9.5 GB | 73 ms · 2.5 GB | 10.4× |
| 4096² | 78,249 ms · 24.0 GB | 311 ms · 10.0 GB | 251× |
The 4096² row is the full decoder’s attention block running out of headroom. A tiled decode would avoid most of it, but tiling the full VAE trades time for seams and complexity.
Gallery
Each image is a FLUX 3 Klein base generation (seed 7, 50 steps). Left of the line: full VAE. Right: our tiny decoder. Drag to compare. Under each is the 384×384 region with the most fine detail, picked automatically, decoded both ways. Numbers are against the full-VAE decode.
6. Does it work for image editing?
FLUX 3 Klein also edits images: it takes up to 10 reference images and a caption, which can include a table of bounding boxes. Editing uses the VAE twice. The encoder turns each reference image into latents the transformer conditions on, and the decoder turns the result back into pixels. My model only replaces the decoder, so I tested three setups:
- A: full VAE encoder and decoder (the baseline).
- B: full VAE encoder, tiny decoder. It decodes the same latent as A, so any difference is decoder error only.
- C: tiny encoder and tiny decoder, an all-tiny pipeline with its own generation.
The tests: a plain edit (recolor a sweater), a text edit, a bounding-box add (put a cat inside a given box) and remove (take out a lamp), and a two-reference composition. “Preserved region” is a part of the image the edit should leave alone, compared with the reference. Same seed everywhere, 50 steps, FLUX 3 Klein base.
| Edit | B vs A | C vs A | Preserved region: A / B / C |
|---|---|---|---|
| Recolor sweater | 0.021 | 0.064 | 0.015 / 0.027 / 0.068 |
| Change chalk text | 0.025 | 0.047 | 0.033 / 0.043 / 0.059 |
| Bbox: add a cat | 0.026 | 0.040 | 0.012 / 0.028 / 0.031 |
| Bbox: remove a lamp | 0.025 | 0.038 | 0.012 / 0.027 / 0.031 |
| Two references | 0.017 | 0.305 | — |
All numbers are LPIPS, lower is better.
- With the full encoder (B), editing works exactly like text-to-image. Every edit lands the same way: the cat is in the same box, the new text is spelled right, the same lamp is gone. The only difference is the decoder’s usual softness, LPIPS 0.017–0.026 against A, the same range as for text-to-image. Bounding-box edits behave no differently, because the boxes live in the caption, which the VAE never sees.
- The preserved regions get slightly softer, not changed. With B, the untouched parts sit about 0.01–0.015 LPIPS further from the reference than with A. That is the tiny decoder’s own error, not the edit leaking.
- Don’t use the tiny encoder for editing. Its latents only roughly match the full encoder’s (cosine 0.90–0.94), and the transformer conditions on them. On single edits that adds drift. With two references the model composed a different picture (different hand pose and framing, LPIPS 0.31), with latents at cosine 0.76 to A’s. I never fine-tuned the encoder, so this is expected. A distilled encoder would be the next thing to train.
Editing the same image again and again
Editing an edit compounds errors. I ran three edits in a row on the portrait (recolor the sweater → add glasses → swap the background), each round feeding its own output back as the next reference:
| Round | B vs A | C vs A |
|---|---|---|
| 1. recolor | 0.021 | 0.064 |
| 2. + glasses | 0.055 | 0.098 |
| 3. + new background | 0.105 | 0.193 |
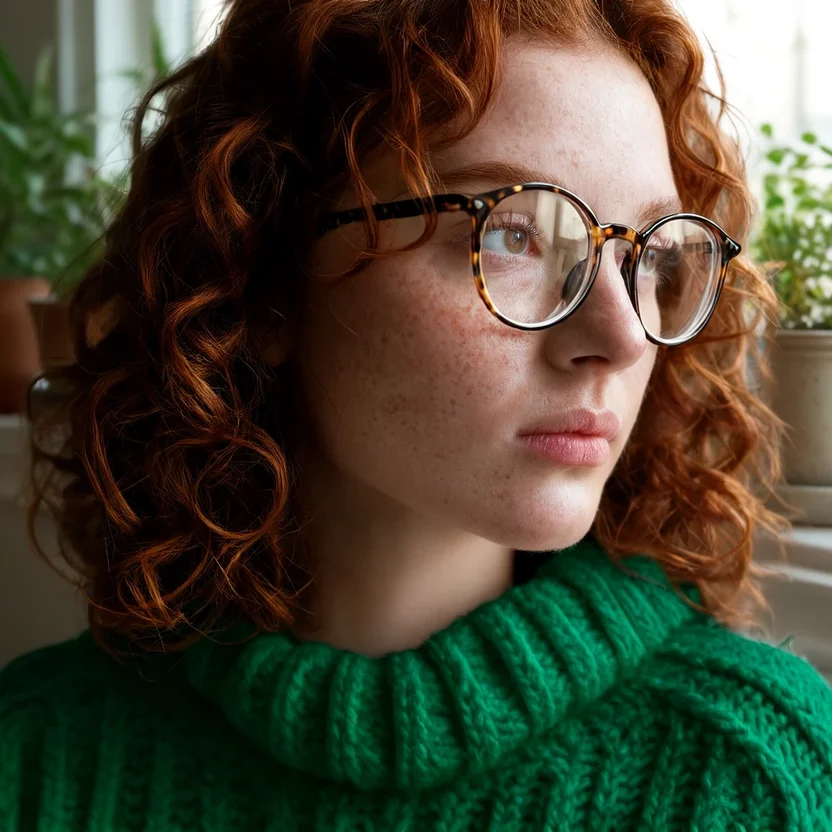 A · full VAE
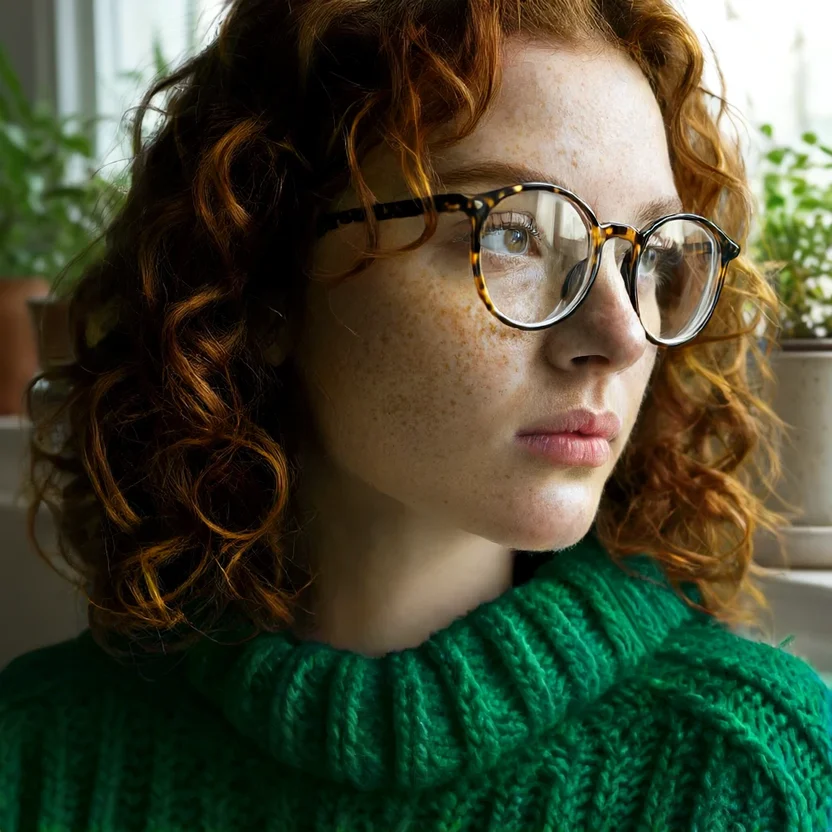 B · tiny decoder
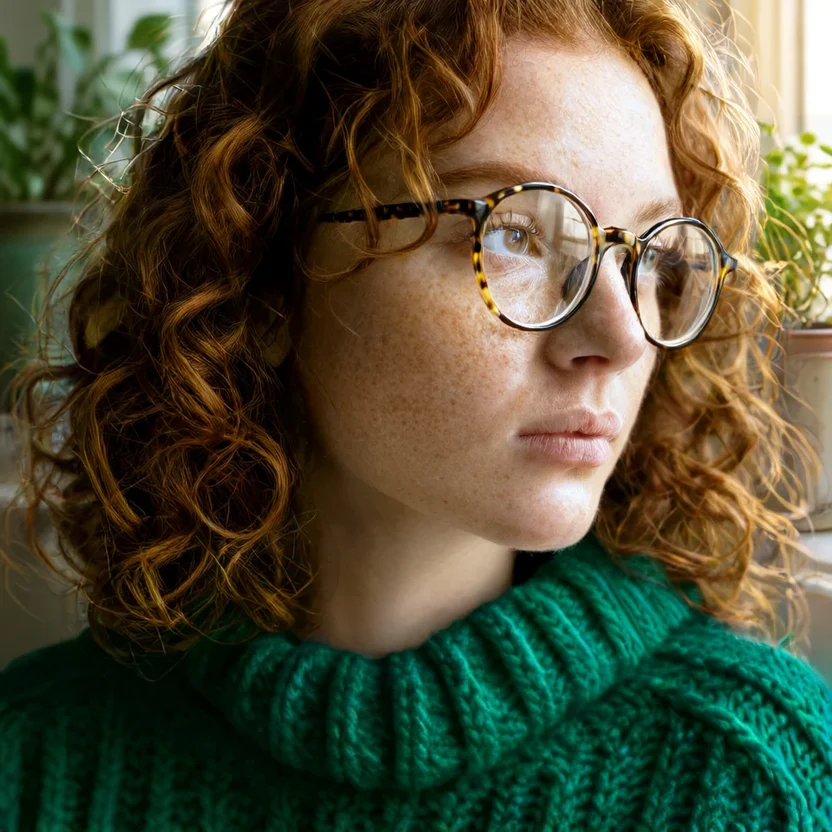 C · all tiny
The drift is not just softness. By round 3, B and C show a visible color and contrast shift. Each round’s small decoder error becomes part of the next reference, and the model faithfully keeps it (“everything else stays unchanged”). For multi-round editing, use the tiny decoder for previews but feed the full-VAE decode back as the next reference. That breaks the loop for the cost of one full decode per round.
7. What worked and what didn’t
Kodak LPIPS of the best checkpoint after each change, lower is better:
| Step | Kodak LPIPS | PSNR |
|---|---|---|
| TAEF2, as released | 0.0380 | 30.69 |
| + fine-tune with L1 + LPIPS on DIV2K (3k steps) | 0.0358 | 32.05 |
| + full data and GAN weight 0.05 | 0.0356 → 0.0377 | 31.71 → 31.24 |
| restart with GAN weight 0.01 | 0.0339 | 31.70 |
| + EMA, 16k steps | 0.0310 | 31.94 |
| + 1024px finish, 3k steps | 0.0306 | 31.98 |
- A strong GAN loss hurt. At weight 0.05 the adversarial term grew as large as L1 and LPIPS combined, and both metrics got worse after 3k steps. At 0.01 it sharpens textures without fighting the reconstruction losses.
- EMA gave the biggest gain. Without it, the Kodak score jumped around by ±0.002 between checkpoints (0.0339 → 0.0356 → 0.0333 → 0.0343). With it, the averaged weights improved almost every evaluation, and beat the raw weights at 15 of the 16 stage-3 checkpoints.
- The PSNR–LPIPS trade-off is real. The first L1-heavy fine-tune had the best PSNR (32.05) but worse LPIPS. The final model gives up 0.07 dB of that PSNR for 15% better LPIPS. I chose by LPIPS because it tracks what people see.
- The 1024px finish helped a little (0.0310 → 0.0306). The model is fully convolutional, so most of what it learns transfers from 512 crops.
8. Limitations
- It is still a 1.34M-parameter decoder. On Kodak it reaches 0.031 LPIPS against the full VAE’s 0.014. Look at the gallery crops: hair, skin pores, neon text and small high-contrast detail come out slightly smoother. For final renders the full VAE is still better. For previews, drafts and memory-limited setups the tiny one is the better trade.
- Tiling is not seamless out of the box. The GroupNorm branch computes image-wide statistics, so decoding tiles separately gives each tile slightly different statistics. Compute those once over the whole latent, or blend overlapping tiles.
- Only the decoder was trained. The encoder is TAEF2’s original and is not good enough to feed editing references (section 6). Keep the full VAE encoder for editing.
- Chained edits drift. Re-editing the tiny decoder’s output compounds into a visible color and contrast shift after a few rounds. Feed full-VAE decodes back instead.
- Evaluation is small. 24 Kodak photos plus 14 generated images, one seed each. The differences are consistent across images, but the exact percentages would move with a bigger set.
- The latent format is inferred, not documented. The VAE file is byte-identical to FLUX.2’s today. A future FLUX 3 VAE update would need a re-check.
9. Reproduce it
- Weights and code: Patil/tiny-flux-klien-3-vae. It contains
tiny_klein3_v2.safetensors, every intermediate checkpoint with its discriminator, the training, evaluation and generation scripts, and the logs. - Use it like TAEF2: build
TAESD(latent_channels=32, arch_variant="flux_2")fromtaesd.py, load the weights, and calldecoder(z_norm). In diffusers, use the wrapper from the TAEF2 model card with this file in place oftaef2.safetensors. - Credits: TAESD and TAEF2 by Ollin Boer Bohan (MIT). FLUX 3 Image Klein by Black Forest Labs (FLUX Kommunity License). Training photos from DIV2K and the Unsplash Lite dataset. This project is not affiliated with or endorsed by Black Forest Labs.